“the cheapest, fastest, and most capable small model we’ve ever released.” — Anthropic, introducing Claude Haiku 5.5
Claude Haiku 5.5 launched on October 7, 2026. Anthropic calls it the cheapest, fastest, and most capable small model they have released so far. It is built for high-volume, cost-sensitive work—summaries, classification, routing, extraction, and quick subagent tasks. For prompts up to 100,000 tokens (the majority of everyday requests), it costs $0.10 per million input tokens and $0.50 per million output tokens. That is a steep drop from Haiku 4.5, and Anthropic says the average cost to run it is around 75 percent lower.
I am not here to rehash the launch benchmarks or the impressive demos. Plenty of people already do that well. I am testing Claude Haiku 5.5 the way most of us will actually use it: on ordinary work, interrupted by real life, with limited time and a strong preference for keeping a human in the loop.
My name is Audrey Finch. I am a content and efficiency coach at a small education company in Cincinnati. I am 38, married, and raising two children ages 7 and 11. My experiments have to survive a busy Tuesday night, a school form that appears at 8:40 p.m., and the fact that I do not want AI to make my life more complicated. I keep a running “friction list” of every repetitive task that steals five minutes or more. That list is what I feed to Haiku 5.5 first.
This post explains why I am starting with ordinary work instead of the flashy demos, what “ordinary” means in practice, how I plan to test, and what you can expect from the rest of this site.
Why Ordinary Work Matters More Than Impressive Demos
Impressive demos are useful. They show the ceiling. They answer the question “What is this model capable of under ideal conditions?” The problem is that most of us do not work under ideal conditions.
Ordinary work is messy. The input is incomplete. The goal is only half-clear. Someone interrupts you halfway through. The output has to be good enough to hand to a colleague or a parent without extensive rewriting. Cost and privacy still matter. And the workflow has to be simple enough that you will actually use it again next week.
When I look at a new model, I ask three practical questions:
Does it reduce real friction in tasks I already do?
How much human correction does it still need?
Is the setup and maintenance cost lower than the time it saves?
Claude Haiku 5.5 is positioned as a fast, affordable model for high-volume and latency-sensitive work. That positioning is exactly why it belongs in ordinary workflows. I do not need it to write a novel or solve an open research problem. I need it to turn a messy to-do list into something I can actually finish, to draft a first-pass parent email, to organize scattered notes from a meeting, or to help a small support team triage routine questions without inventing policy.
The demos often skip the maintenance part. They show a perfect prompt and a clean output. In real life the prompt drifts, the context changes, and the model’s strengths and weaknesses become clearer only after a few dozen runs. That is the part I want to document.
What “Ordinary Work” Looks Like in Practice
Here is the kind of work I am testing first. None of it is exotic.
Personal and household
Turning a brain dump of tasks into a realistic weekly plan that accounts for school pickup, meetings, and the fact that I will be interrupted.
Comparing grocery options or planning five family meals from what is already in the pantry.
Turning repeated notes (packing lists, school forms, recurring chores) into reusable checklists.
Writing and content
Drafting clear internal updates or parent-facing explanations without sounding corporate.
Turning interview or meeting notes into a structured first draft that still needs human judgment.
Summarizing long documents while flagging claims that need verification.
Small-team and support-adjacent
First-draft replies for routine customer or parent questions, with a clear human-review checklist.
Building simple internal FAQ drafts from existing documentation.
Classifying or routing repetitive requests so a five-person team spends less time on the same questions.
These tasks share a few traits. They are frequent. The stakes are real but not usually catastrophic. A good-enough draft is valuable if it is fast and cheap. And a bad draft is easy to catch if a human stays in the loop.
I am deliberately starting with tasks that live on my friction list rather than tasks designed to make the model look smart. If Haiku 5.5 cannot help with the ordinary ones, the impressive demos do not matter much to me.
How I Will Test (and What I Will Report)
I follow a simple, repeatable approach so the results stay useful over time.
Define the real task and the real constraints.
What is the actual input? How messy is it? How much time do I have? Who will see the output? What would “good enough” look like?Run the workflow under ordinary conditions.
I use the same tools and interruptions I face on a normal day. No cleaned-up data. No perfect quiet environment.Record what happened.
Speed, quality of the first draft, number and type of corrections needed, any privacy or cost notes, and whether I would actually use the workflow again.Separate observation from judgment.
I mark the test date. I distinguish what the model produced from what I decided after reviewing it. I note failure points clearly.Decide the boundary.
Every useful post ends with two short sections: “When I would use this” and “When I would not use this.” That boundary is more valuable than a glowing review.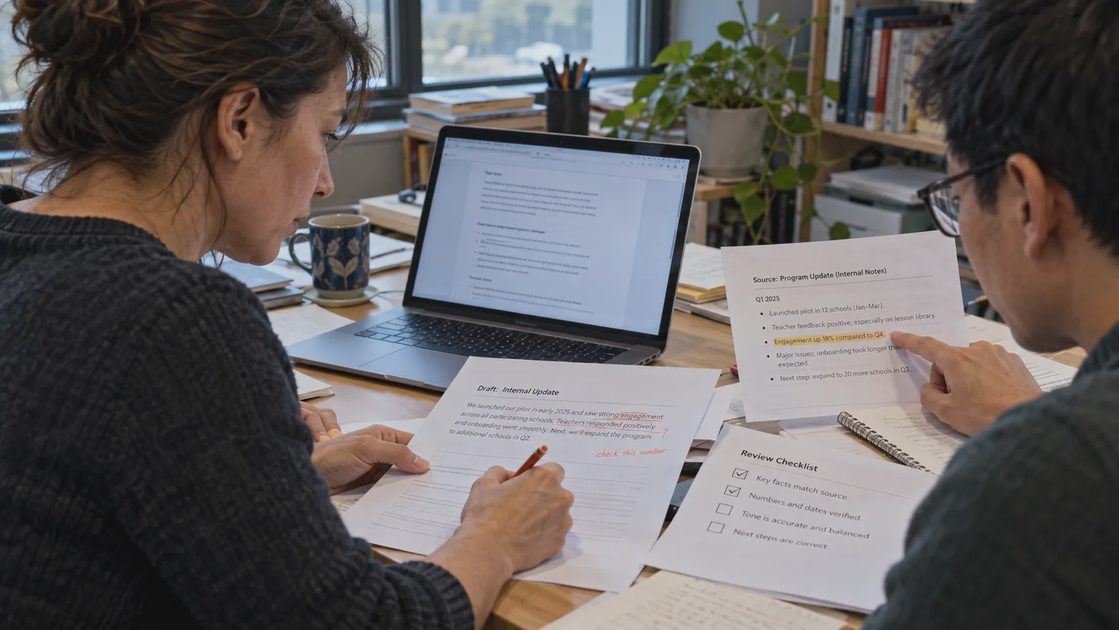
I will not claim a workflow “works” until I have run it enough times to see the patterns. One perfect run is a demo. Ten runs with interruptions is closer to real life.
Privacy is non-negotiable. I never paste private household details, student information, customer data, or company documents into examples. When I need realistic input, I anonymize or invent clearly labeled sample text that matches the shape of the real problem without containing real data.
What You Can Expect From This Site
Haiku for Real is not another list of magic prompts. It is a place for practical Claude Haiku 5.5 workflows tested against ordinary work and small-team constraints.
The four main sections are:
Everyday Haiku — personal productivity, writing, planning, and household administration.
Study and Research Desk — learning, note-taking, source-based research, and keeping independent thinking intact.
Small Team Systems — support triage, content operations, internal knowledge, and lean SaaS workflows.
The Honest Test — side-by-side runs, failure analysis, cost notes, and what breaks after a couple of weeks.
Every guide will show the setup, the result, the corrections, and the limitations. I will keep the human-in-the-loop principle visible: “Make the useful part easy—and keep a human in the loop.”
I will also refresh high-value posts when model behavior or pricing changes. Claude Haiku 5.5 is new. Pricing, limits, and capabilities can shift. When they do, the articles will be updated and the change noted.
Why a Fast, Affordable Model Changes the Calculation
Before Haiku 5.5, many people treated the cheapest models as “good enough for classification and not much else.” The gap between small models and the mid-tier models was large enough that you often paid the higher price just to avoid constant rewriting.
The new pricing and the reported gains on knowledge-work and agentic benchmarks change that math for high-volume, repeatable tasks. For a parent planning meals, a freelancer turning notes into drafts, or a five-person support team handling routine questions, the cost of trying a solid workflow is now low enough that the experiment itself is cheap.
That does not mean the model is magic. It still needs clear instructions, realistic expectations, and human review. Speed and low cost make it easier to keep the human in the loop because you are not burning budget every time you ask for a revision.
When I Would Reach for Haiku 5.5 First
I reach for it when:
The task is frequent and relatively bounded.
A fast first draft or structured summary is more valuable than a polished final product.
Cost and latency matter more than maximum capability on any single request.
I can design a simple review step that catches the most common failure modes.
I reach for a stronger model when:
The stakes are high and the cost of a subtle error is large.
The task requires deep multi-step reasoning or long, coherent writing with few revisions.
I need the model to hold a complex set of constraints without frequent human correction.
Those boundaries will become clearer as I run more tests. They are not fixed. They depend on the task, the version of the model, and how carefully the workflow is designed.
A Note on Expectations
I will not tell you that Claude Haiku 5.5 will change everything. I will not hide the times it needs heavy editing or produces confident-sounding mistakes. I will not recommend a workflow I have not actually tried under ordinary conditions.
What I will do is show the useful part clearly, document the friction that remains, and help you decide whether the workflow is worth keeping in your own stack.
If you are an ordinary user—professional, parent, student, freelancer, educator, or someone on a small team—who wants practical help without becoming a prompt engineer, this site is written for you.
The next posts will move from the “why” into the first concrete workflows. I will start with the simplest useful ones: turning a messy to-do list into a realistic week, a beginner’s first 30 minutes with the model, and a few household and writing tests that survived real interruptions.
Test date for this framing post: October 12, 2026. Model version and pricing will be checked again before any hands-on results are published.
Make the useful part easy—and keep a human in the loop. That is the standard I am holding myself to, and the standard I hope these guides will help you hold too.
No letters yet — be the first to write.